Evan Lee Salim
Artificial intelligence is not only reshaping industries and daily life but is simultaneously forging an entirely new vocabulary to describe its rapid evolution. From boardrooms to research labs, an increasingly complex lexicon of acronyms and technical terms, such as LLMs, RAG, and RLHF, has become commonplace. The introduction of concepts like "opaque recurrence" — a reasoning technique deployed in OpenAI’s new Astra model that has reportedly rattled AI safety researchers as of last week — underscores the dizzying pace of linguistic innovation. This swift emergence of specialized terminology can leave even seasoned tech professionals feeling uncertain, highlighting a critical need for clear, accessible definitions to bridge the knowledge gap.
This evolving glossary aims to provide clarity, offering plain-English explanations of the AI terms most frequently encountered by developers, investors, and general enthusiasts alike. As the field progresses at an unprecedented rate, this document is designed to be a living resource, mirroring the dynamic nature of the AI systems it describes.
The Genesis of a New Dialect: AI’s Linguistic Explosion
The proliferation of AI-specific language is a direct consequence of the technology’s accelerated development and its multidisciplinary nature. AI draws from computer science, mathematics, neuroscience, linguistics, and philosophy, each contributing its own conceptual frameworks and terminologies. The rise of large language models (LLMs) in particular, exemplified by the public debut of models like ChatGPT in late 2022, catalyzed a surge in public and corporate engagement with AI, pushing these once-esoteric terms into mainstream discourse. The sheer scale of innovation, from foundational research to practical applications, necessitates new descriptors for novel architectures, training methodologies, and emergent behaviors.
Understanding this lexicon is no longer merely an academic exercise; it is essential for informed decision-making across various sectors. Investors need to grasp the technical nuances of a startup’s pitch, developers require precise terms to collaborate effectively, and policymakers must comprehend the implications of AI systems to legislate responsibly. The linguistic challenge mirrors the technological one: how to keep pace with a field that is redefining its own boundaries almost daily.
Foundational Concepts: Building Blocks of AI Understanding
At the heart of AI lies a set of fundamental concepts that underpin its operation and ambition. Artificial General Intelligence (AGI) remains a highly debated and somewhat nebulous term, yet it represents the ultimate aspiration for many AI researchers. Generally, AGI refers to AI systems that possess cognitive capabilities comparable to, or exceeding, those of an average human across a wide spectrum of tasks. OpenAI CEO Sam Altman once characterized AGI as the "equivalent of a median human that you could hire as a co-worker," while OpenAI’s charter defines it as "highly autonomous systems that outperform humans at most economically valuable work." Google DeepMind offers a slightly different perspective, viewing AGI as "AI that’s at least as capable as humans at most cognitive tasks." This variation in definition underscores the conceptual fluidity even among leading experts, indicating the complexity of defining such a transformative future state.
The backbone of modern AI, particularly generative AI, is Deep Learning. This subset of machine learning employs multi-layered Artificial Neural Networks (ANNs), structures inspired by the interconnected neurons of the human brain. These networks enable algorithms to identify complex correlations in vast datasets, far beyond the capabilities of simpler machine learning models. Deep learning models autonomously extract features from data and learn from errors, iteratively refining their outputs. However, their efficacy is contingent on enormous volumes of data—often millions or more data points—and they typically demand substantial computational resources and longer training times, leading to higher development costs. The computational power, often referred to as Compute, is the lifeblood of this industry, provided by specialized hardware like GPUs, CPUs, and TPUs that form the bedrock of AI infrastructure.
The process by which AI models acquire their capabilities is known as Training. This involves feeding vast amounts of data into a model, allowing it to learn patterns and generate useful outputs. For instance, training an image recognition model might involve showing it millions of labeled pictures of cats until it can reliably identify a cat in new images. Training is compute-intensive and costly, prompting the adoption of strategies like Transfer Learning. This technique leverages a pre-trained model as a starting point for a new, related task, reapplying previously acquired knowledge to shortcut development and conserve resources, especially when data for the new task is limited. After training, the operational phase, where the AI model is put to use to make predictions or draw conclusions from new data, is called Inference. This is where the learned patterns are applied, with the speed and efficiency of inference heavily dependent on the underlying hardware and the model’s size.
The parameters within an AI model that determine the importance given to different features in the training data are called Weights. These numerical values are continuously adjusted during training to optimize the model’s output, ensuring it aligns more closely with the desired outcomes. For example, in a housing price prediction model, weights would reflect how factors like the number of bedrooms, bathrooms, or the presence of a garage influence property value based on historical data.
Advanced Architectures and Reasoning Techniques
The current AI landscape is dominated by Large Language Models (LLMs), the foundational technology behind popular AI assistants such as ChatGPT, Claude, Google Gemini, and Meta’s Llama. LLMs are deep neural networks comprising billions of numerical parameters (weights) that learn the intricate relationships between words and phrases, constructing a multidimensional representation of language. Trained on colossal datasets of text from books, articles, and transcripts, LLMs predict the most probable sequence of words to generate responses to user prompts.
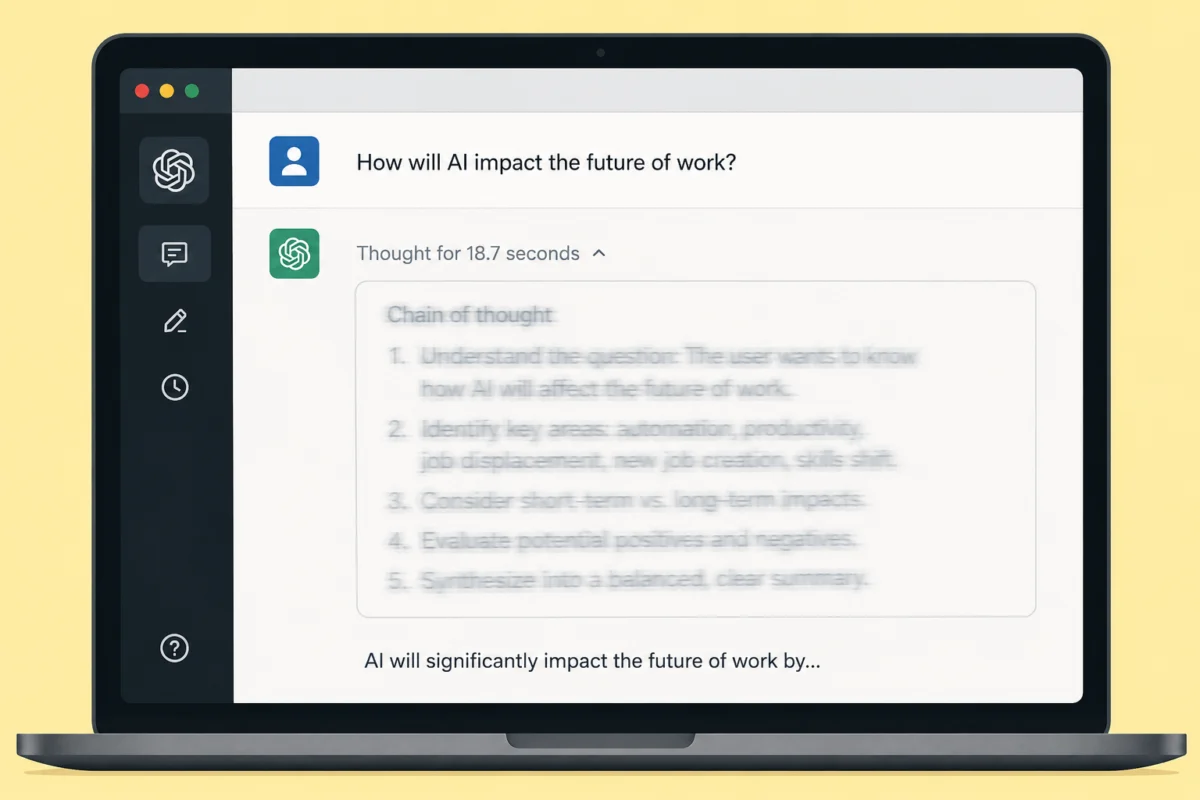
Enhancing the reasoning capabilities of LLMs is a critical area of research. Chain of Thought reasoning, for instance, breaks down complex problems into smaller, sequential steps, mimicking human problem-solving. This approach, while requiring more processing time, significantly improves the accuracy of answers, particularly in logical or coding contexts. Reasoning models optimized for chain-of-thought thinking are developed from traditional LLMs through techniques like reinforcement learning.
A more recent and controversial development is Opaque Recurrence, sometimes referred to by the engineering term Recurrent Depth. This technique involves an AI model repeatedly looping the same query through its internal layers rather than engaging in explicit, step-by-step reasoning in plain language. While it promises greater efficiency and allows smaller models to achieve outsized performance with less compute, it drastically reduces the human-readable traces of the model’s thought process. This raises significant concerns for AI safety researchers, as these logs are crucial for identifying and mitigating misbehavior, making oversight much harder. This opaque process has fueled fears of Neuralese, a hypothetical worst-case scenario where an AI model reasons entirely in its internal numeric representations, rendering its thinking an inscrutable "black box" to humans. While no shipped model currently operates solely in Neuralese, the emergence of techniques like opaque recurrence is seen by some safety experts as a concerning step in that direction, prompting calls for greater transparency and explainability.
Further advancements in model architecture include Mixture of Experts (MoE). This innovative approach segments a neural network into numerous smaller, specialized sub-networks, or "experts." For any given task, a built-in "router" activates only a select few of these specialists. This method allows for the creation of enormous models that remain relatively fast and cost-effective to run, as only a fraction of the network is actively engaged at any one time. Mistral AI’s Mixtral model is a prominent example, and OpenAI’s newer GPT models are widely believed to incorporate similar strategies, though not officially confirmed.
Operational Efficiency and System Integration
The practical deployment of AI involves a host of techniques aimed at improving efficiency and integration. Distillation is a process used to extract knowledge from a large "teacher" AI model to train a smaller, more efficient "student" model. By recording the teacher’s outputs and using them to train the student, developers can create compact models that approximate the larger model’s behavior with minimal performance loss. This technique is believed to have been instrumental in developing faster versions of frontier models, like OpenAI’s GPT-4 Turbo. However, using distillation to replicate a competitor’s model via their API can violate terms of service, leading to investigations as seen with DeepSeek and OpenAI.
Fine-tuning is another crucial technique, involving further training an AI model on specialized, task-oriented data to optimize its performance for a specific domain or application. Many AI startups leverage existing LLMs as a base, then fine-tune them with proprietary datasets to create commercial products tailored for niche sectors, enhancing utility and reducing hallucinations.
The efficiency of AI operations is also boosted by Memory Cache, an optimization technique designed to make inference more efficient. By saving particular calculations for future user queries, caching reduces the computational load and power consumption required to generate responses. Key-value (KV) caching, prevalent in transformer-based models, exemplifies this, significantly accelerating response times by minimizing redundant algorithmic labor.
Integrating AI models with external systems is facilitated by technologies like API Endpoints. These function as "buttons" that allow other software programs or AI agents to interact with a system, pulling data or controlling third-party services autonomously. As AI agents become more sophisticated, their ability to discover and utilize these endpoints independently opens up powerful, albeit sometimes unpredictable, possibilities for automation in smart homes and enterprise applications. The Model Context Protocol (MCP), an open standard introduced by Anthropic and now managed by the Linux Foundation, acts as a "USB-C port for AI." It enables AI models to connect seamlessly to external tools and data sources—such as files, databases, or applications like Slack and Google Drive—without the need for custom connectors for every pairing. Its rapid adoption by major players like OpenAI, Google, and Microsoft underscores its significance in standardizing AI integration.
The fundamental unit of human-AI communication, bridging the gap between human language and algorithmic processes, is the Token. These discrete segments of data are created through tokenization, breaking down raw text into digestible units for language models. In commercial contexts, tokens also determine cost, with most AI companies charging for LLM usage on a per-token basis. Consequently, Token Throughput, a measure of how much AI work a system can handle simultaneously, is a critical performance metric. Maximizing token throughput is an obsession for AI infrastructure teams, as it directly impacts how many users a model can serve concurrently and the speed of their responses.
Emergent Behaviors and Societal Implications
The rapid evolution of AI brings forth both immense potential and significant challenges. AI Agents represent a new frontier, referring to tools that autonomously perform a series of tasks on a user’s behalf, extending beyond basic chatbot functionalities to actions like booking tickets or maintaining code. While the infrastructure for their full capabilities is still developing, the concept implies autonomous systems capable of drawing on multiple AI components to execute multi-step tasks. A specialized version, Coding Agents, can autonomously write, test, and debug code across entire codebases, handling iterative development with minimal human oversight. While acting as tireless interns, human review remains essential for quality and safety.
Generative Adversarial Networks (GANs), a machine learning framework, have been pivotal in creating realistic data, including deepfake technologies. GANs involve two neural networks—a generator and a discriminator—locked in a competitive training process. The generator attempts to produce realistic output, while the discriminator tries to identify artificially generated data. This adversarial dynamic refines outputs to be highly realistic without additional human intervention, though GANs excel in narrower applications like image or video generation. The technology underpinning many modern art-, music-, and text-generating AI models is Diffusion. Inspired by physics, diffusion systems learn to "destroy" data by adding noise, then master a "reverse diffusion" process to reconstruct the data from noise, thereby gaining the ability to generate new, coherent outputs.
A persistent challenge in AI quality is Hallucination, the industry’s term for AI models generating incorrect or fabricated information. This can lead to misleading and potentially dangerous outputs, from harmful medical advice to factual inaccuracies. Hallucinations are thought to arise from gaps in training data and are driving a trend toward more specialized and vertical AI models, aiming to reduce knowledge gaps and disinformation risks.
The debate between Open Source and closed-source AI models is a defining one in the industry. Open-source models, like Meta’s Llama family, make their underlying code publicly available, fostering collaborative development, accelerating progress, and enabling independent safety audits. In contrast, closed-source models, such as OpenAI’s GPT series, keep their code private, allowing users to interact with the product but not inspect its internal workings. This distinction has profound implications for transparency, accessibility, and the future direction of AI research and deployment.
Reinforcement Learning is a powerful training paradigm where an AI system learns by trial and error, receiving "rewards" for correct actions. Unlike supervised learning, it allows models to explore environments and continuously update their behavior based on feedback. Techniques like Reinforcement Learning from Human Feedback (RLHF) are now central to fine-tuning LLMs, making them more helpful, accurate, and safe by aligning their behavior with human preferences and values.
Looking further ahead, Recursive Self-Improvement (RSI), much like AGI, describes a threshold for AI intelligence and autonomy. In an RSI scenario, AI models begin to improve themselves without human intervention, leading to a dramatic acceleration in capabilities. While some view this as a potentially "cataclysmic" moment akin to the singularity, many startups pursuing RSI frame it as the next frontier in research, focusing on the more tangible goal of an AI model designing its own successor.
Economic and Infrastructure Realities
The relentless demand for computational power has led to unprecedented strains on global supply chains. A new term, RAMageddon, encapsulates the severe and escalating shortage of Random Access Memory (RAM) chips. The insatiable appetite of major tech companies and AI labs for RAM to power their data centers has created a bottleneck, driving up prices and impacting industries from gaming, which has seen console price increases, to consumer electronics, where memory shortages could lead to significant dips in smartphone shipments. This supply crisis is expected to persist, highlighting the physical constraints underpinning the digital revolution.
The ability to perform many computations simultaneously, known as Parallelization, is fundamental to both training and inference in AI. Modern GPUs, designed for parallel processing, have become the hardware backbone of the industry. As AI systems grow in complexity, efficient parallelization across multiple chips and machines is paramount for rapid and cost-effective model development and deployment, making research into better parallelization strategies a field in itself.
During training, researchers closely monitor Validation Loss, a numerical indicator of how well an AI model is learning. A lower validation loss signifies better learning. This metric is crucial for determining when to halt training, adjust hyperparameters, or investigate potential issues like overfitting, where a model memorizes its training data rather than genuinely learning generalizable patterns.
Conclusion: Navigating the Future’s Language
The rapid expansion of AI’s specialized vocabulary is more than a linguistic phenomenon; it reflects the profound and accelerating transformation occurring across technology, economy, and society. From the aspirational heights of AGI to the immediate concerns of opaque recurrence and RAMageddon, each term encapsulates a piece of the complex puzzle that is modern AI. For individuals and organizations alike, mastering this evolving lexicon is no longer optional but imperative for informed participation in the AI revolution. As AI systems continue their exponential growth, the language used to describe them will undoubtedly continue to evolve, demanding continuous learning and adaptation to truly understand the world that AI is actively rewriting.